MangoBoost expands into AI inference services, unveils ‘Mango Inference’
- Input
- 2026-10-12 14:34:11
- Updated
- 2026-10-12 14:34:11
Use AI without building servers... manage operations in one place
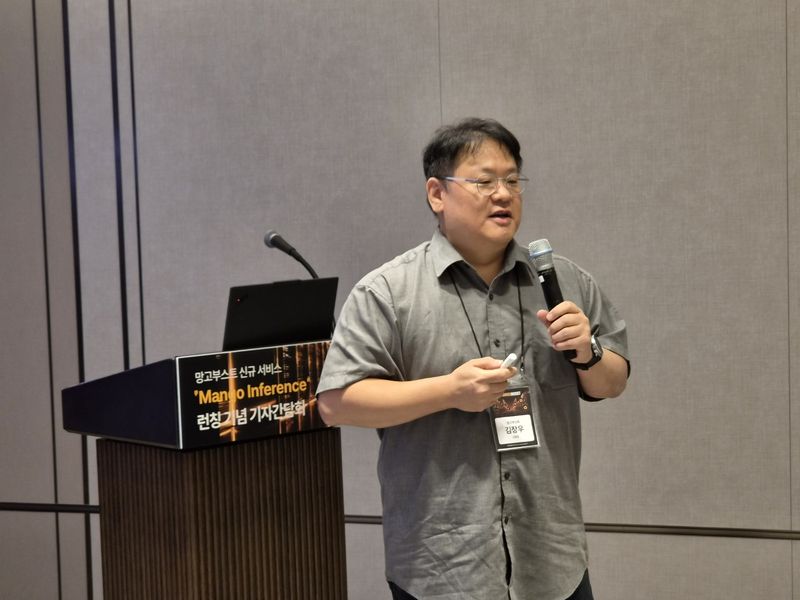
MangoBoost CEO Kim Jang-woo held a press conference on the 12th at the Grand InterContinental Seoul Parnas in Gangnam-gu, Seoul, to launch the new service. “Mango Inference stands out for its full-stack technology, which we designed in-house from hardware to software,” he said. “We will set a new standard for fast, efficient and reliable inference.”Unveiled that day, Mango Inference is a serverless AI inference platform that reduces the burden of building and managing servers. Users can access AI models without complex infrastructure setup by obtaining an API key, an authentication code required to access the service.
MangoBoost is targeting system integration (SI) partners, developers and startups as its main customers, aiming to reduce response latency, increase throughput and lower total cost of ownership (TCO). Mango Inference lets users select AI models, check usage, response speeds and costs, and manage authentication codes all in one place. The company also plans to offer dedicated inference services tailored to individual customers in the future.
Kim said the company gave existing customers free credits before launch so they could try the service. He said MangoBoost focused on providing services tailored to customers’ preferred models, processing performance and prices, and that the response had been positive.
MangoBoost expects the launch to serve as a springboard for expanding its business—from supplying GPU servers, storage devices and software separately to providing inference services. Emphasizing that the company puts software on computers it designs in-house and provides services directly to customers, Kim said, “We’re an AI factory company.”
Reducing data-processing bottlenecks... expanding proprietary AI infrastructure
MangoBoost improves efficiency by optimizing not only the computing performed by individual GPUs but also the movement of data from storage to GPUs. Its core software, LLMBoost, reduces bottlenecks throughout the inference service pipeline. “Buying another GPU just because you need more memory is a very cost-inefficient way to scale,” Kim said. “Our proprietary networking technology lets us expand memory separately.”MangoBoost also cited its partnership with AMD as a key competitive advantage. The company said it has improved inference performance in setups that connect multiple AMD GPUs or use GPUs from different generations together.
The company also plans to expand its own service infrastructure. Kim said it is building a 1-megawatt (MW) system near Dosan Park in Seoul’s Gangnam district and is developing infrastructure with a capacity of 1–5 MW over this year and next. The company will install GPUs through colocation, receiving power, space and other resources, and plans to gradually reduce its reliance on the external cloud services it currently uses alongside its own infrastructure.
Kim said the company plans to secure hundreds of AMD’s latest GPUs, with dozens already secured. He added that it aims to complete the GPU procurement by the first quarter of next year at the latest.
[email protected] Yoon Hong-jip Reporter